Qwen3.8-27B AP
Same size, same speed, closer to the model Qwen actually trained. Requants of Qwen3.8-27B published on HuggingFace, benchmarked byte-for-byte against Unsloth's UD builds at identical file sizes.
These are the highest-precision quants of Qwen3.8-27B I can produce byte-for-byte: standard GGUF, no fork, no special flags, drop into any current llama.cpp build. I measure fidelity with KL divergence against the unquantized BF16 model, on a held-out technical-prose corpus, a neutral web-text corpus, and wikitext-2. Across the sizes I've tested, these builds beat both ISTA and Unsloth's UD lineup, pushing the size-vs-fidelity pareto frontier out further than either.
Every AP tier shows lower KL divergence than the size-matched Unsloth UD build, on the same held-out corpus, same revision, same llama.cpp converter, no fork. The gap widens as the tiers get smaller: 5.1% at Q4_K_XL, 10.4% at IQ3_S.
Full lineup
| Build | Format | Size | VRAM | Target |
|---|---|---|---|---|
| AP-Q4_K_XL (most headroom) | GGUF, mainline-compatible | 16.35 GiB | ~18 GiB | Any llama.cpp build, -ngl 999 |
| AP-Q4_K_M (recommended) | GGUF, mainline-compatible | 15.33 GiB | ~17 GiB | Any llama.cpp build, -ngl 999 |
| AP-IQ4_XS | GGUF, mainline-compatible | 13.27 GiB | ~15 GiB | 16 GB systems |
| AP-Q3_K_XL | GGUF, mainline-compatible | 12.24 GiB | ~14 GiB | 16 GB+, longer context |
| AP-IQ3_S | GGUF, mainline-compatible | 11.21 GiB | ~13 GiB | 12 GB, balanced |
| AP-IQ3_XS | GGUF, mainline-compatible | 10.70 GiB | ~12.5 GiB | Multi-model setups |
| AP-IQ3_XXS | GGUF, mainline-compatible | 10.00 GiB | ~12 GiB | 12 GB, minimal |
| AP-IQ2_S (smallest) | GGUF, mainline-compatible | 8.95 GiB | ~10.9 GiB | Smallest footprint |
| mmproj-BF16 | Vision encoder | 0.87 GiB | +0.9 GiB | Add for image input |
Calibrated on the Bartowski and Thireus imatrix corpora plus a third of wikitext-2's training articles, 6,012 documents and 4.67M characters in total. Built and verified with my own Rust tooling, agention-infer.
Running it
Stock GGUF, converted from Qwen3.8-27B with llama.cpp's own converter, no changes, no fork. Any current llama.cpp build loads it directly.
llama-server -hf agentionai/Qwen3.8-27B-AP-GGUF:IQ4_XS \
  --jinja -ngl 999 -fa on -c 32768 -ctk q8_0 -ctv q8_0
Add mmproj-BF16.gguf for image input:
llama-server -hf agentionai/Qwen3.8-27B-AP-GGUF:IQ4_XS \
  --mmproj mmproj-BF16.gguf --jinja -ngl 999 -fa on -c 32768
Thinking is on by default. Keep the KV cache at q8_0 or f16, lower than that and reasoning quality degrades. Also runs through Ollama, LM Studio, and vLLM.
Does it hold up in real use? A one-shot coding test
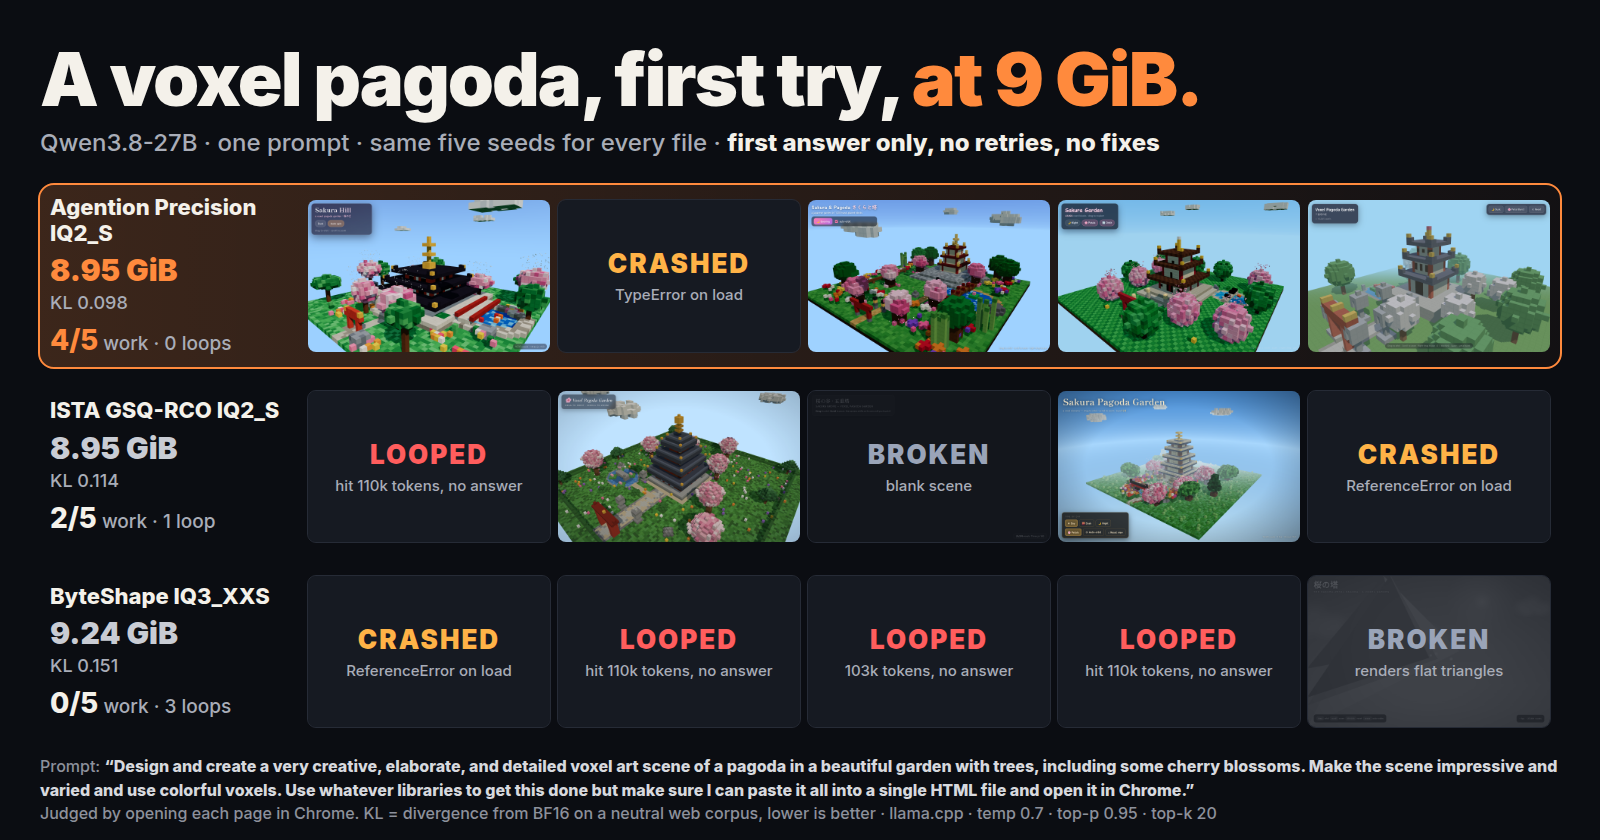
Numbers only tell you so much, so I ran a plain sanity check: same prompt, same five seeds, every tier, first answer only, no retries and no fixes. Each output opened in Chrome and judged by eye. Below is what AP-IQ2_S, the smallest tier at 8.95 GiB, produced on its first try.